Having fun with large integers and prime numbers
For quite some time I have wondered about why Mathematica (add link to article about my programming languages) is rather slow when it comes to integer factorization.
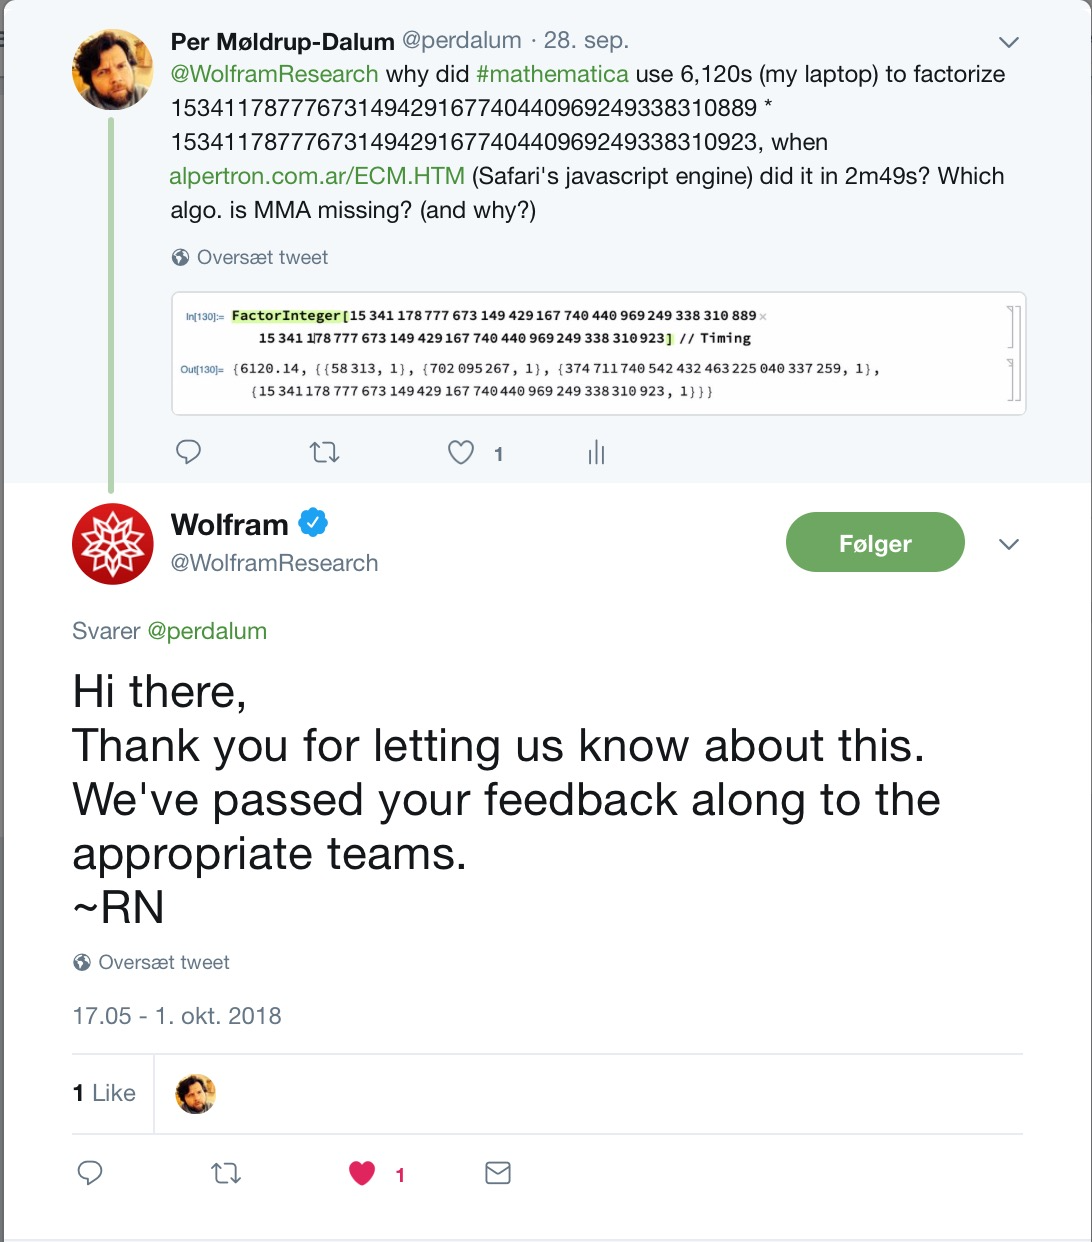
A few years ago, one of my friends Thomas Egense implemented the bigmathfast Java library for working with large integers including integer factorization utilizing the PollardRho and ECM/Siqs algorithms. Back then, we created some large integers that were the product of two prime numbers, and then used the library to factorize them and comparing the results with PARI/GP and Mathematica. I also ran the tests in Julia and Maple, but I lost the results and none of them could compete with PARI/GP or `bigmathfast` nor were as slow as Mathematica.
I’ve now systematized this work and created a GitHub repository, Testing Prime Factorization, so it’s much easier to redo and extend.
Results
So, how fast or slow are PARI/GP and Mathematica now? I ran the benchmark suite on my MacBook M2 24GB RAM.
MacBook Air M2 24GB
Output columns are number of digits and run time measured in milliseconds. For Mathematica I stopped at 70 digits, as the calculation time became too long to wait for.
    >: wolframscript -version
    WolframScript 1.13.0 for Mac OS X ARM (64-bit)

    >: wolframscript -f factorize.wls large-ints-5.txt;echo "80   NA\n90   NA" > wls.out; cat wls.out
    30   19.692
    40   80.359
    50   1583.59
    60   17965.5
    70   377270.
    80    NA
    90    NA


     >: gp --version
                      GP/PARI CALCULATOR Version 2.17.2 (released)
             arm64 running darwin (aarch64/GMP-6.3.0 kernel) 64-bit version
         compiled: Feb 28 2025, Apple clang version 17.0.0 (clang-1700.3.19.1)
                               threading engine: pthread
                    (readline v8.3 disabled, extended help enabled)

    $ LARGE_INTS=large-ints-7.txt gp -q factorize.gp 2>/dev/null > gp.out; cat gp.out
    30	4
    40	18
    50	149
    60	1628
    70	11339
    80	270966
    90	3604437

    #bigmathfast-1.0-jar-with-dependencies.jar

    ./factorize-bigmathfast.py large-ints-7.txt > bmf.out; cat bmf.out
    30	64
    40	181
    50	965
    60	3654
    70	18411
    80	283088
    90	3503897
With the output in three data files, it can be compared against e.g., PARI/GP as the baseline.
>: paste gp.out bmf.out wls.out|cut -f1,2,4,6| awk 'BEGIN {OFS="|"} NR<6 {print $1,$2/$2,$3/$2,$4/$2} NR>5 {print $1, $2/$2,$3/$2,"NA"}'|sed 's/^/|/;s/$/|/'|pbcopy
| no. of digits | PARI/GP | bigmathfast | Wolfram |
|---|---|---|---|
| 30 | 1 | 16 | 4.923 |
| 40 | 1 | 10.0556 | 4.46439 |
| 50 | 1 | 6.47651 | 10.6281 |
| 60 | 1 | 2.24447 | 11.0353 |
| 70 | 1 | 1.62369 | 33.2719 |
| 80 | 1 | 1.04474 | NA |
| 90 | 1 | 0.972107 | NA |
PARI/GP is the baseline, and the numbers indicate how faster PARI/GP is. E.g., for a 30-digit integer, PARI/GP is 16 times faster than bigmathfast and 4.923 times faster than Wolfram. The relative slowness of bigmathfast for small integers is probably due to start-up time for the Java VM.
What did I learn?
- How to write scripts in PARI/GP
- how to use the
pastecommand - That Mathematica is just slow at this specific task 🤷♂️ (I have another small performance tests coming up and this time Mathematica is the fast kid on the track)
- A bit more Python (add link to article on my programming languages.)
- A bit more awk
Future Work
- A more robust benchmark (then again, why? I just need the gist of which is fastest and don't want to write benchmark tests)
- Go spelunking into the PARI/GP and Java code to learn how this is done. Learn about the PollardRho and ECM/Siqs algorithms.